When we have an AI analyze a thick document or solve a complex problem through multiple steps, does the model need to remember every bit of the conversation accurately from beginning to end? According to experimental results published in November 2026 by NVIDIA researchers (Peter Belcak et al., 12 authors), modern AI models can maintain task accuracy almost intact even when they continuously summarize and compress conversation content. Interestingly, whether the input document is long or short, the number of tokens actually consumed during the AI interaction showed no significant difference. 1, 2
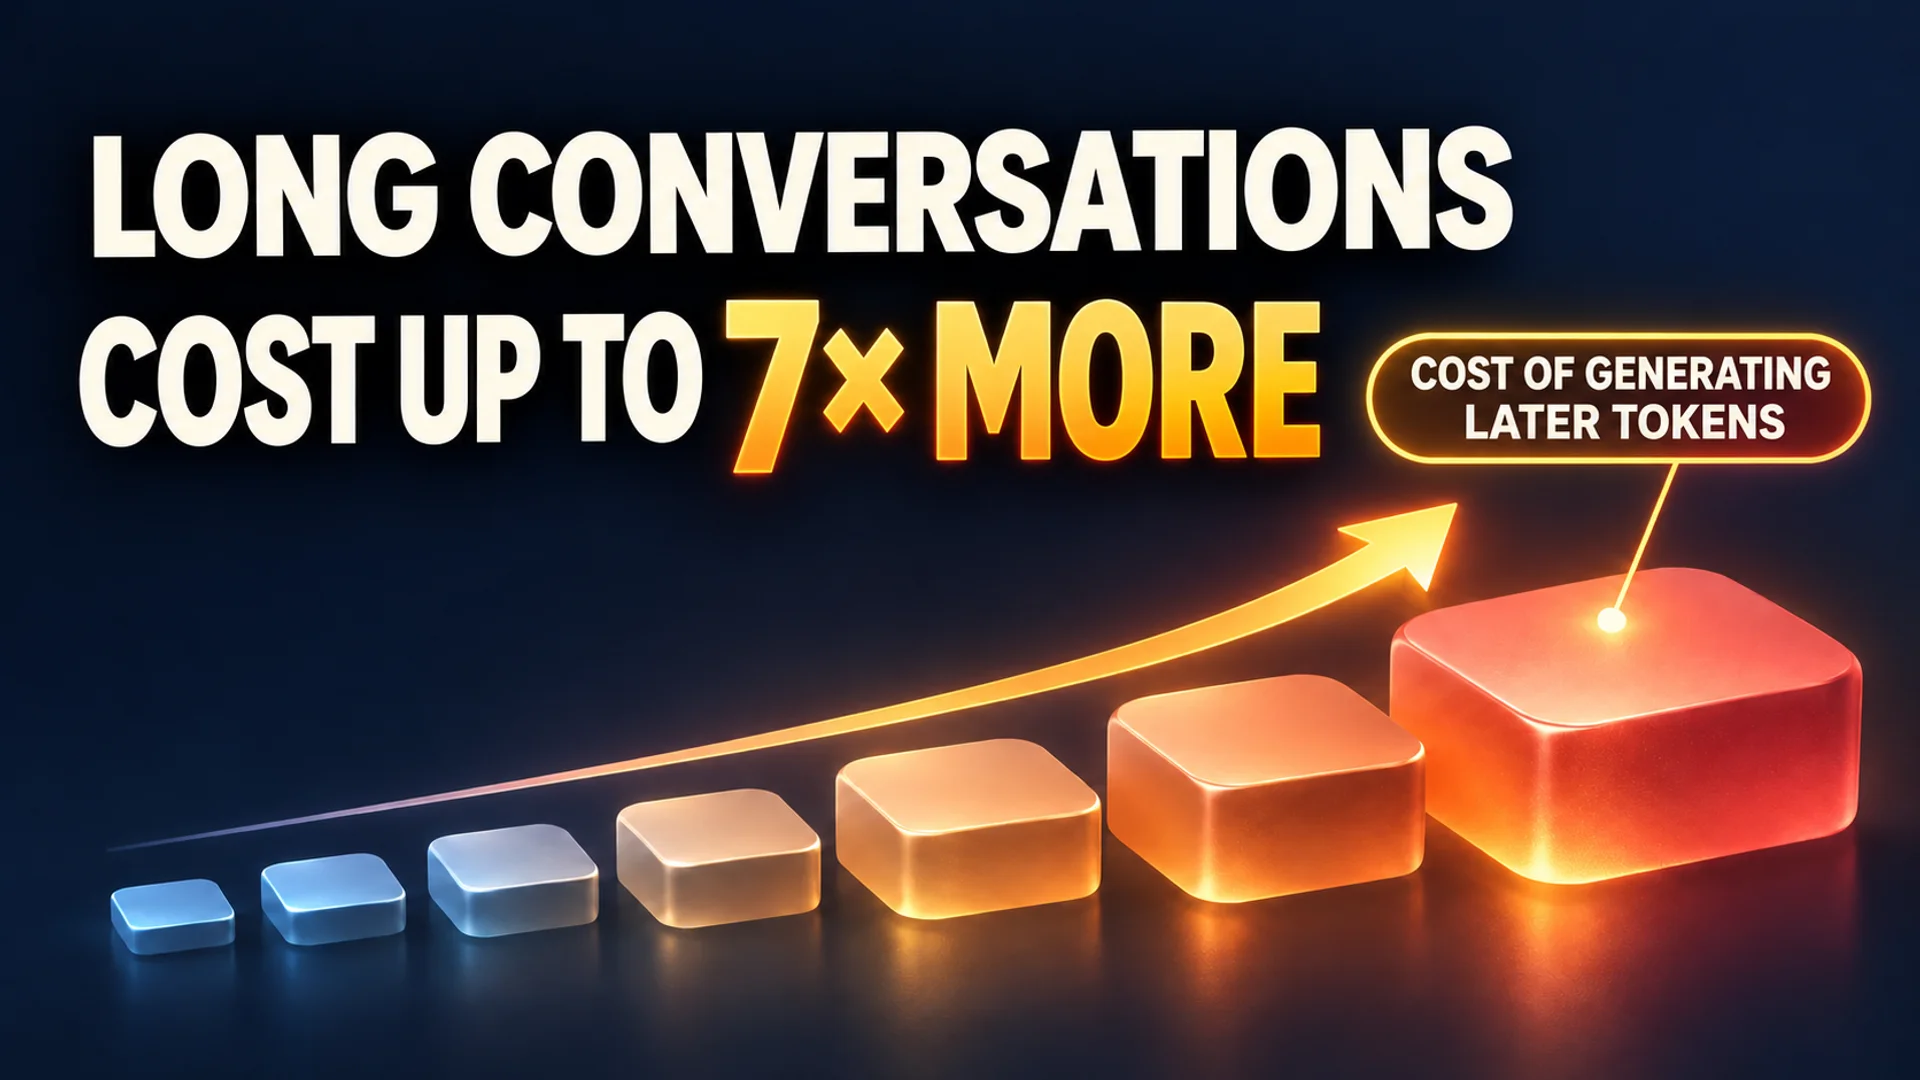
This study suggests that endlessly increasing the "context window" (the amount of information a model can reference at once) is not the solution and can instead increase unnecessary costs. In particular, for frontier-class open-weight models (high-performance models with public weights), the cost of generating tokens at the latter part of the conversation history can be up to seven times higher than the earlier part, making efficient context management crucial. 2
The Structure of Increasing Costs in Long Conversations and Cost Disparity
When conversing with an AI, the text we input or the AI generates is processed in units called "tokens." As the AI creates an answer, it adds tokens one by one. Researchers discovered that as the conversation history grows longer, the computational cost of generating tokens at the latter part of the sequence increases sharply. 2
For frontier open-weight models, the cost difference for generating tokens between the beginning and the end of a conversation can widen to as much as sevenfold. 2 This implies that continuously accumulating all conversation content without compression can be highly inefficient in terms of computational resources. Especially when analyzing documents exceeding hundreds of thousands of words or performing software development tasks spanning dozens of steps, context management strategies have become necessary to resolve issues related to cost and speed.
Three Context Management Strategies and Experimental Results
To verify performance differences based on how context is managed, NVIDIA researchers proposed and compared three strategies in a controlled experiment. According to community summaries and related reports, these three strategies are as follows. 1
- Full History Accumulation (FHA): This method continues to accumulate the entire history without deleting or summarizing the conversation content.
- End-of-Context Compression (EoCC): This method summarizes the entire conversation at specific intervals and then starts a new conversation based on the summary. This is one of the methods widely adopted currently.
- Semantic State Update (SAC): This is an extreme compression method that updates only the core progress (semantic state) up to the current point, rather than saving the entire conversation, and performs actions step-by-step.
Experimental results confirmed that for modern frontier models, excluding the 'FRAMES' benchmark, there is no significant loss in task accuracy even when content is periodically compressed (Method 2). In some models, such as Claude Opus 4.5, performance actually improved with compression. 1 A particularly noteworthy point is the relationship between input data length and actual conversation costs. The number of tokens actually used during AI interaction was nearly the same regardless of whether the input document was long or short. 1 The paper interprets this to mean that a long input does not necessarily require a long context; it is more efficient to distinguish between information that is always needed and information that can be retrieved when needed, thereby keeping the context short.
| Compression Strategy | Mechanism | Key Observations |
|---|---|---|
| FHA | Continuously accumulates conversation history without compression | Baseline revealing surging token costs 1 |
| EoCC | Periodically summarizes entire conversation and starts new session | Maintained or improved accuracy in frontier models, excluding FRAMES 1 |
| SAC | Updates and accumulates only 'semantic state' after performing actions | Significantly reduced context length, maintained accuracy 1, 2 |
'What to Keep' Determines the Success of Compression Strategies
This efficiency does not apply uniformly to all models. The researchers experimented with small open-weight models in a local environment allocated 109GB of memory. 1 The results showed that models like Qwen 3.6 27B and MiniMax M2.7 operated stably even with periodic compression methods. 1 However, the Qwen 3 Coder Next model exhibited a phenomenon where performance plummeted from 53 points to 3.6 points during the compression process. 1
Researchers pointed out that the cause of performance degradation might be the failure to retain sufficient core and useful information from verbose reasoning during compression. 1 Ultimately, it is not merely a question of whether to compress or not, but the mechanism determining 'what to keep and what to discard' during compression is closely linked to the model's inherent summarization capability. This is an important consideration when handling long documents in local environments.
SSSM Proposal and Industry's Hardware Response
Based on these findings, NVIDIA researchers proposed a concept called 'Semantic State Space Model (SSSM).' This involves training a loop where the model takes a natural language description of the current state as input, performs an action, and updates only the meaningful state reflecting the result. 1, 2 Although this is still at the proposal stage, it presents a new direction for managing long contexts.
Meanwhile, the industry is redesigning the hardware layer to address the memory bottleneck caused by long conversations. According to TrendForce research, NVIDIA announced a dedicated storage platform called 'CMX' in January 2026 to expand the memory hierarchy between local SSDs and shared storage in response to massive KV cache storage demands for AI inference. 3 This demonstrates the construction of physical infrastructure to efficiently manage the surging demand for key-value caches during AI inference. 3
While the industry increases hardware capacity to manage costs, this study demonstrated the efficiency of a 'retrieve when needed' approach at the software level. The conclusion of this experiment is that for frontier models, excluding the FRAMES benchmark, AI does not need to remember long documents entirely; periodic and extreme compression strategies can significantly reduce context length while maintaining task accuracy almost intact. However, as seen in local small model experiments, models with insufficient summarization capabilities may experience significant performance fluctuations during compression. The paper adds that maintaining a short context can be practically useful even if explicit compression training was not included in the training process.
References
- 일반 긴 컨텍스트에 집착하지 마라(NVIDIA, arXiv 2026.11.) · arca.live↩
- You don't need long context · arxiv.org↩
- 2026 Trends: Memory for New AI Inference Demand | TrendForce · trendforce.com↩